Still have questions?
Talk with our team
Product questions, pricing, or rollout — we'll get back within one business day.
Contact usBlueprint vision
Junzhe Shi, Yuan Gan, and Shida Jiang
Computer Vision (cs.CV) arXiv:2610.09313 [cs.CV]
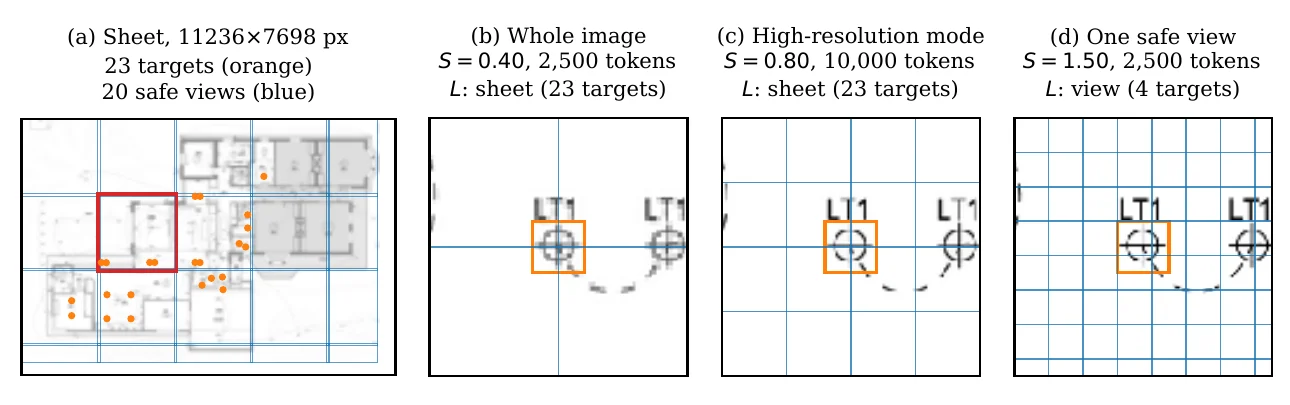
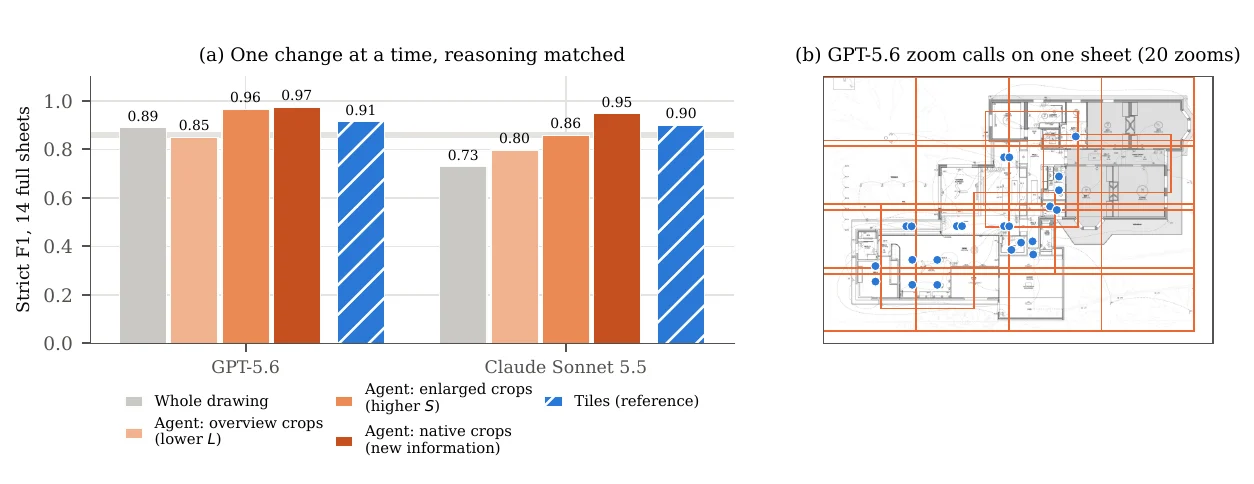
Vision-language models (VLMs) often miss small objects in large images. We ask three questions: what limits them, which of these limits better models can remove, and whether the classical way of handling large images, local decomposition, still has a future. We answer them with a theory built on two quantities of the image interface: S, the number of visual tokens across an object's side, and L, the content a call must cover. A W × H image sent whole within N tokens gives an object of side m at most m√(N/(WH)) tokens per side. Doubling the token budget N therefore raises the largest S a whole image can reach by only 41%, and seeing an image at the S an object needs costs at least on the order of S² tokens, whatever the model. If recognition improves gradually with S, any search strategy, zoom agents included, obeys a recall-cost frontier. What better models can change is the S an object needs and how much one call can carry, measured in bits per object found; the coverage cost remains. Decomposition still has a future. Assuming only that more tokens per object and less content per call do not hurt on average, splitting an image cannot lower expected recall if no view zooms out relative to the whole image and views overlap by one object. Neither part can be dropped. The cost of every such decomposition is bounded, and a simple rule approaches the bound as the image grows. The theory is tested in about 177,000 requests on 797 images. On controlled images, none of 40 orderings predicted for 8 VLMs is violated. Checked after the fact on drawings, floor plans, natural and synthetic images, 61 of 89 implied orderings hold significantly and 4 fail, all for OpenAI models given more pixels than their default path. On construction drawings the rule never significantly lowered recall relative to the whole image and raised it by up to 0.28. Code and data: https://github.com/shijunzhe/vlm-small-objects.
Still have questions?
Product questions, pricing, or rollout — we'll get back within one business day.
Contact usLive walkthrough
See takeoff, estimates, and bid management tailored to how your team works today.
Schedule demo